摘要
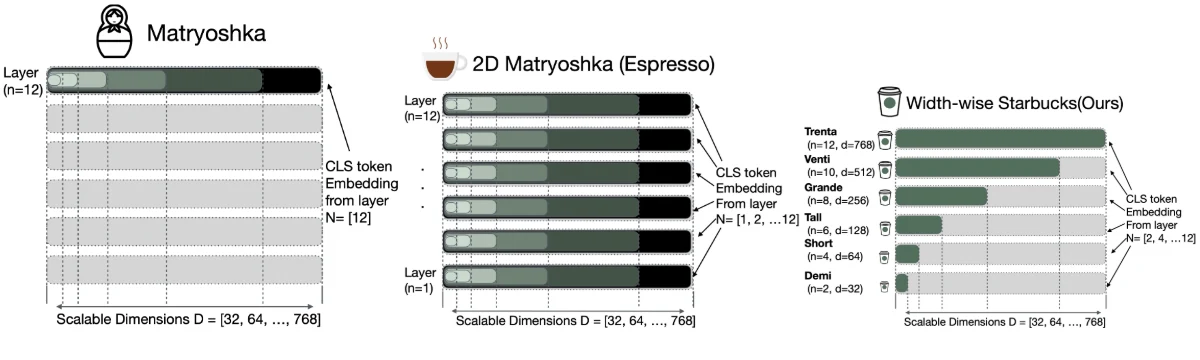
Effective approaches that can scale embedding model depth (i.e. layers) and embedding size allow for the creation of models that are highly scalable across different computational resources and task requirements. While the recently proposed 2D Matryoshka training approach can efficiently produce a single embedding model such that its sub-layers and sub-dimensions can measure text similarity, its effectiveness is significantly worse than if smaller models were trained separately. To address this issue, we propose Starbucks, a new training strategy for Matryoshka-like embedding models, which encompasses both the fine-tuning and pre-training phases. For the fine-tuning phase, we discover that, rather than sampling a random sub-layer and sub-dimensions for each training steps, providing a fixed list of layer-dimension pairs, from small size to large sizes, and computing the loss across all pairs significantly improves the effectiveness of 2D Matryoshka embedding models, bringing them on par with their separately trained counterparts. To further enhance performance, we introduce a new pre-training strategy, which applies masked autoencoder language modelling to sub-layers and sub-dimensions during pre-training, resulting in a stronger backbone for subsequent fine-tuning of the embedding model. Experimental results on both semantic text similarity and retrieval benchmarks demonstrate that the proposed pre-training and fine-tuning strategies significantly improved the effectiveness over 2D Matryoshka models, enabling Starbucks models to perform more efficiently and effectively than separately trained models.
相关论文
2026ECIR 2026被引 15 次共同一作
Starbucks: Improved Training for 2D Matryoshka Embeddings
Shengyao Zhuang*, Shuai Wang*, Bevan Koopman, Guido Zuccon
2025SIGIR 2025被引 14 次第一作者
2D Matryoshka Training for Information Retrieval
Shuai Wang, Shengyao Zhuang, Bevan Koopman, Guido Zuccon