摘要
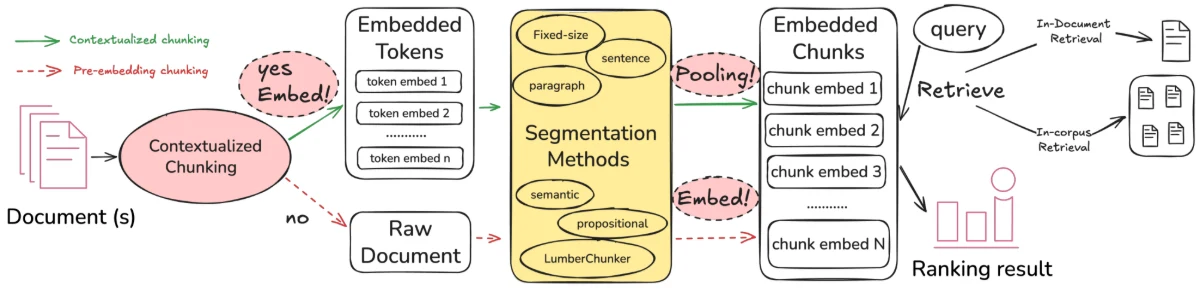
Document chunking is a critical preprocessing step in dense retrieval systems, yet the design space of chunking strategies remains poorly understood. Recent research has proposed several concurrent approaches, including LLM-guided methods (e.g., DenseX and LumberChunker) and contextualized strategies (e.g., Late Chunking), which generate embeddings before segmentation to preserve contextual information. However, these methods emerged independently and were evaluated on benchmarks with minimal overlap, making direct comparisons difficult. This paper reproduces prior studies in document chunking and presents a systematic framework that unifies existing strategies along two key dimensions: (1) segmentation methods, including structure-based methods (fixed-size, sentence-based, and paragraph-based) as well as semantically-informed and LLM-guided methods; and (2) embedding paradigms, which determine the timing of chunking relative to embedding (pre-embedding chunking vs. contextualized chunking). Evaluation covers both in-document retrieval (needle-in-a-haystack) and in-corpus retrieval settings. Key finding: simple structure-based methods outperform LLM-guided alternatives for in-corpus retrieval, while LumberChunker performs best for in-document retrieval. Contextualized chunking improves in-corpus effectiveness but degrades in-document retrieval.
相关论文
2026SIGIR 2026被引 9 次共同一作
Beyond Chunk-Then-Embed: A Comprehensive Taxonomy and Evaluation of Document Segmentation Strategies for Information Retrieval
Yongjie Zhou*, Shuai Wang*, Bevan Koopman, Guido Zuccon