摘要
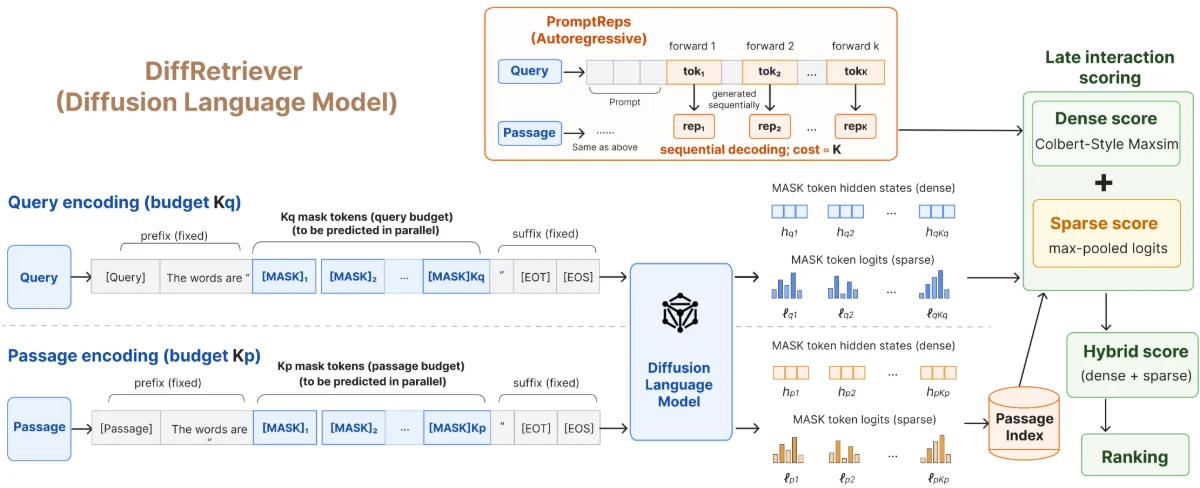
This paper shows how diffusion language models (DLMs) can be used as effective and efficient retrievers. Existing DLM-based retrievers (e.g., DiffEmbed) follow BERT-style encoding, representing each query or passage as a single mean-pooled vector. This ignores how DLMs are trained to generate responses through masked-position prediction under bidirectional attention, a capability that can provide stronger retrieval signals. We propose DiffRetriever, which uses the DLM's native masked-position prediction directly for retrieval. For each query or passage, DiffRetriever appends one or more masked positions, using the outputs as retrieval representations in a single forward pass. With one masked position, single-representation DiffRetriever already improves over DiffEmbed on the same backbones. DiffRetriever also naturally extends to multi-representation retrieval: DLMs process multiple masked positions jointly, enabling ColBERT-style fine-grained matching with little additional encoding latency. In autoregressive LLM retrievers, the same multi-representation strategy requires sequential decoding and therefore incurs much higher latency. DiffRetriever obtains the strongest aggregate effectiveness within our matched comparison, outperforming DiffEmbed, PromptReps, and RepLLaMA. Masked-position counts selected on training data transfer well across datasets, while per-query variation suggests headroom for adaptive allocation. Code is available at https://github.com/ielab/diffretriever.
相关论文
2026arXiv被引 1 次第一作者
DiffRetriever: Parallel Representative Tokens for Retrieval with Diffusion Language Models
Shuai Wang, Yu Yin, Shengyao Zhuang, Bevan Koopman, Guido Zuccon