摘要
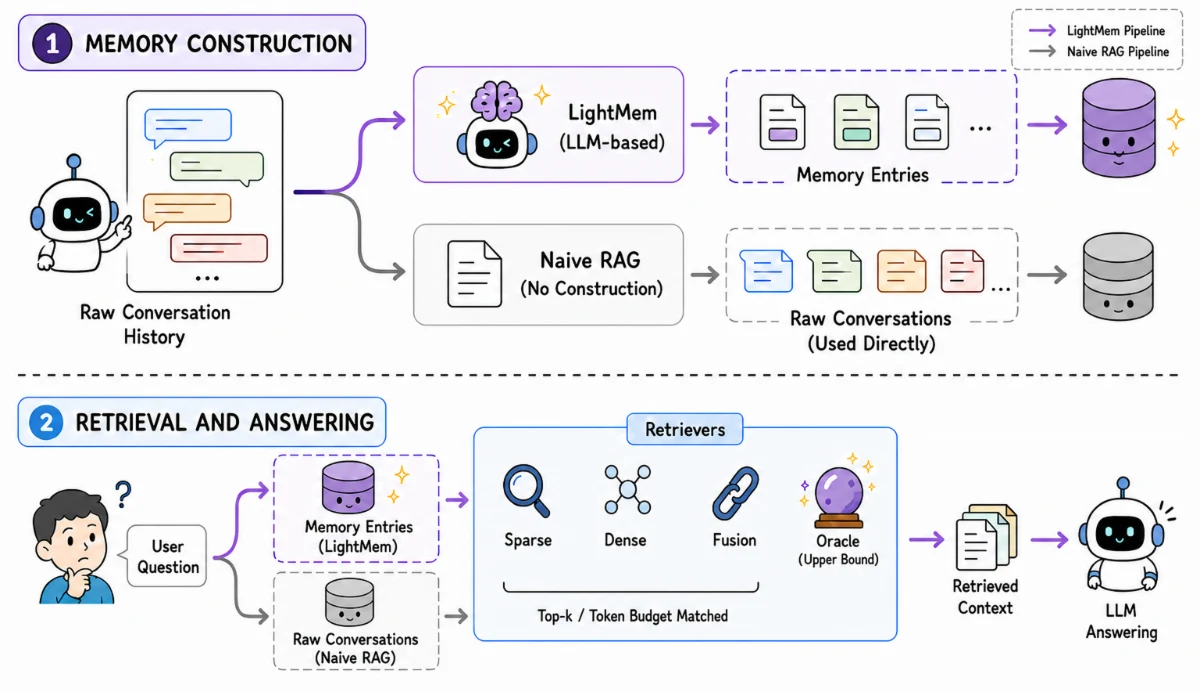
This reproducibility study examines memory management in conversational agents. We compared LightMem, a lightweight memory-construction approach, against Naive RAG, which retrieves directly from raw dialogue turns. Our findings show that retriever selection significantly impacts performance, with accuracy ranging from 58.1% to 75.5% depending on the retriever used. Contrary to expectations, constructed memories don't consistently outperform raw-turn retrieval. LightMem offers a context-efficiency trade-off rather than a general advantage over simpler approaches. Performance advantages depend on specific retriever configurations and token budget constraints, suggesting that future research should focus on optimizing retrieval and reranking strategies rather than complex memory construction methods.
相关论文
2026SIGIR-AP 2026
Reproducing LightMem: Naive RAG Is Just as Good for Memory Management
Yongjie Zhou, Shuai Wang, Bevan Koopman, Guido Zuccon