2026SIGIR 2026ShortRetrievers and rerankerscited 121×
Rank-R1: Enhancing Reasoning in LLM-based Document Rerankers via Reinforcement Learning
Shengyao Zhuang, Xueguang Ma, Zheng Yao, Shuai Wang, Bevan Koopman, Jimmy Lin, Guido Zuccon
Proceedings of the 49th International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR 2026)
Abstract
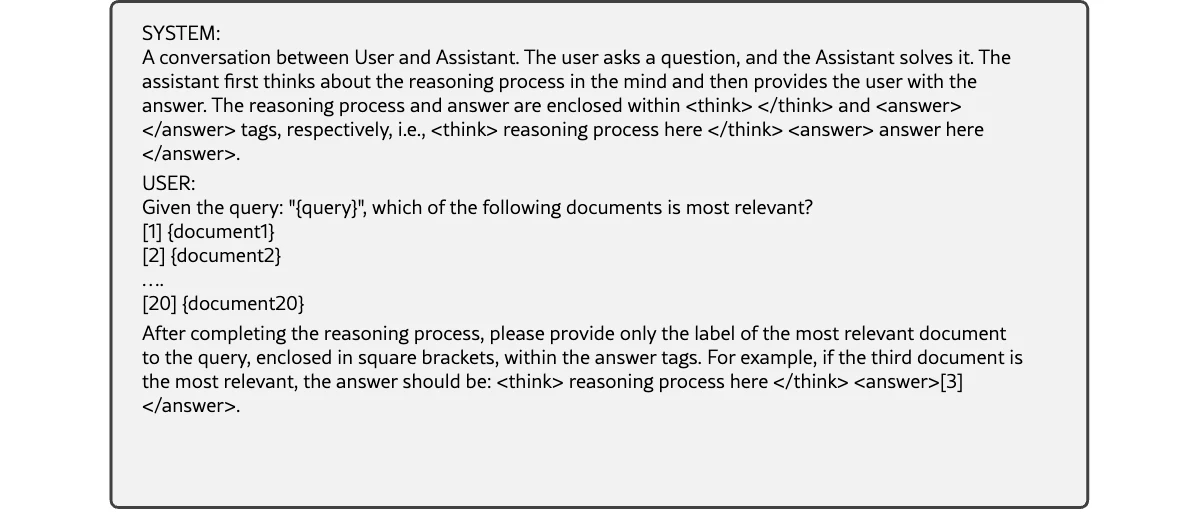
This paper introduces Rank-R1, a novel LLM-based reranker that performs reasoning over both the user query and candidate documents before performing the ranking task. Existing document reranking methods based on LLMs typically rely on prompting or fine-tuning to order or label candidate documents. For Rank-R1, a reinforcement learning algorithm (specifically Group Relative Policy Optimization, GRPO) is used along with only a small set of relevance labels — without any reasoning supervision — to enhance the reasoning ability of LLM-based rerankers. Given a query and candidate documents, the reranker generates reasoning steps before selecting the most relevant document; the reward signal is determined only by whether the model correctly identifies the most relevant document. Experiments on TREC DL and BRIGHT datasets show Rank-R1 achieves in-domain effectiveness at par with supervised fine-tuning using only 18% of the training data, and largely outperforms zero-shot and fine-tuned baselines on out-of-domain complex-query datasets, with the 14B model surpassing zero-shot GPT-4 on BRIGHT. Reasoning also improves explainability of ranking results.
Cite · BibTeX
@inproceedings{zhuang2026rank,
  title = {{Rank-R1: Enhancing Reasoning in LLM-based Document Rerankers via Reinforcement Learning}},
  author = {Shengyao Zhuang and Xueguang Ma and Zheng Yao and Shuai Wang and Bevan Koopman and Jimmy Lin and Guido Zuccon},
  booktitle = {Proceedings of the 49th International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR 2026)},
  year = {2026},
  url = {https://arxiv.org/abs/2503.06034}
}