Retrievers and rerankers · 2025
ReSLLM
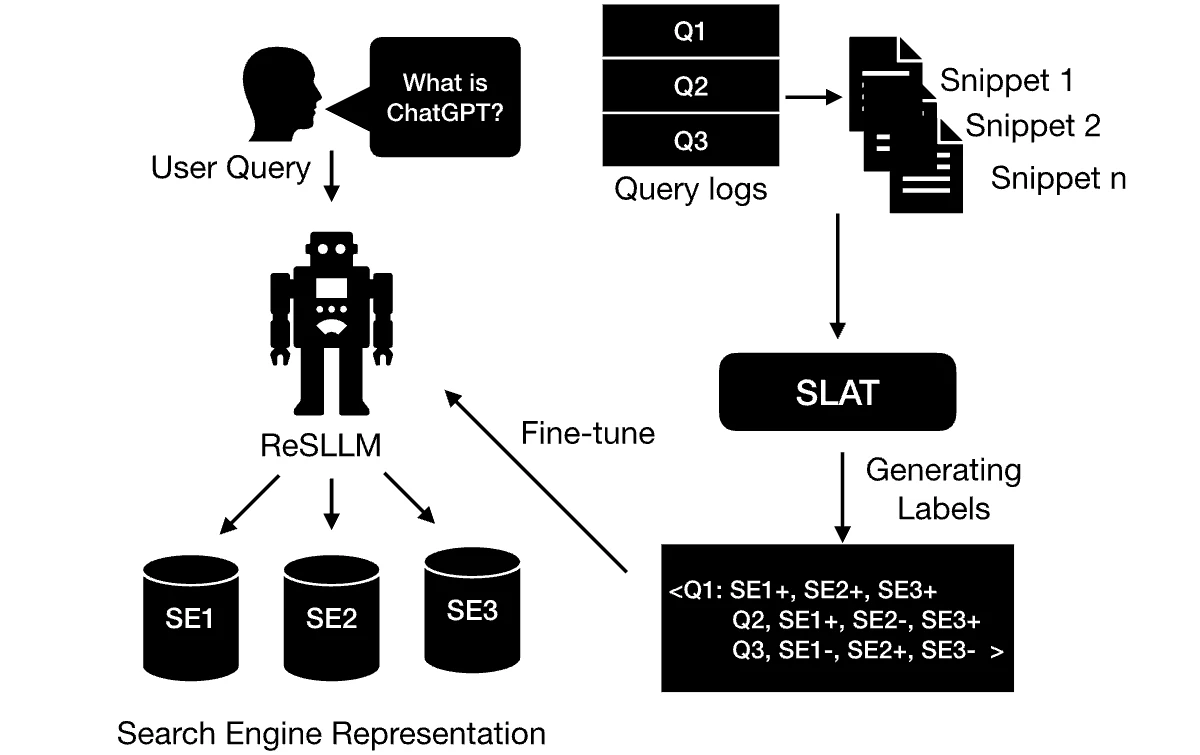
Using language models to select resources for federated search, including the SLAT fine-tuning protocol.
Abstract
Federated search, which involves integrating results from multiple independent search engines, will become increasingly pivotal in the context of Retrieval-Augmented Generation pipelines empowering LLM-based applications such as chatbots. These systems often distribute queries among various search engines, ranging from specialized (e.g., PubMed) to general (e.g., Google), based on the nature of user utterances. A critical aspect of federated search is resource selection - the selection of appropriate resources prior to issuing the query to ensure high-quality and rapid responses, and contain costs associated with calling the external search engines. However, current SOTA resource selection methodologies primarily rely on feature-based learning approaches. These methods often involve the labour intensive and expensive creation of training labels for each resource. In contrast, LLMs have exhibited strong effectiveness as zero-shot methods across NLP and IR tasks. We hypothesise that in the context of federated search LLMs can assess the relevance of resources without the need for extensive predefined labels or features. In this paper, we propose ReSLLM. Our ReSLLM method exploits LLMs to drive the selection of resources in federated search in a zero-shot setting. In addition, we devise an unsupervised fine tuning protocol, the Synthetic Label Augmentation Tuning (SLAT), where the relevance of previously logged queries and snippets from resources is predicted using an off-the-shelf LLM and then in turn used to fine-tune ReSLLM with respect to resource selection. Our empirical evaluation and analysis details the factors
Papers
2025WWW 2025cited 22×First author
ReSLLM: Large Language Models are Strong Resource Selectors for Federated Search
Shuai Wang, Shengyao Zhuang, Bevan Koopman, Guido Zuccon
Retrievers and rerankers
Retrievers and rerankers · 2026
DiffRetriever
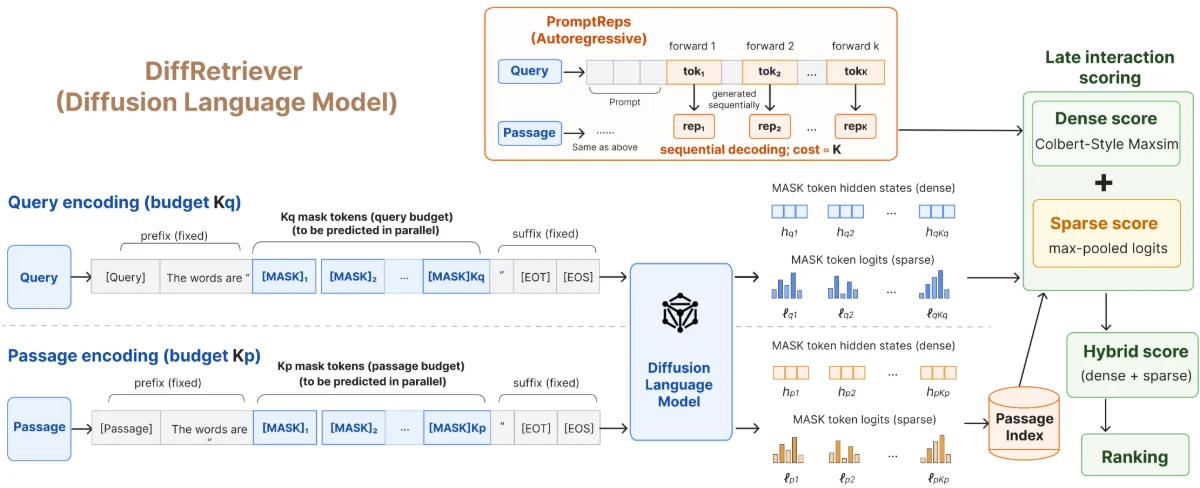
Parallel masked positions in a diffusion language model produce multiple representations for dense and sparse retrieval.
Retrievers and rerankers · 2026
Beyond Chunk-Then-Embed
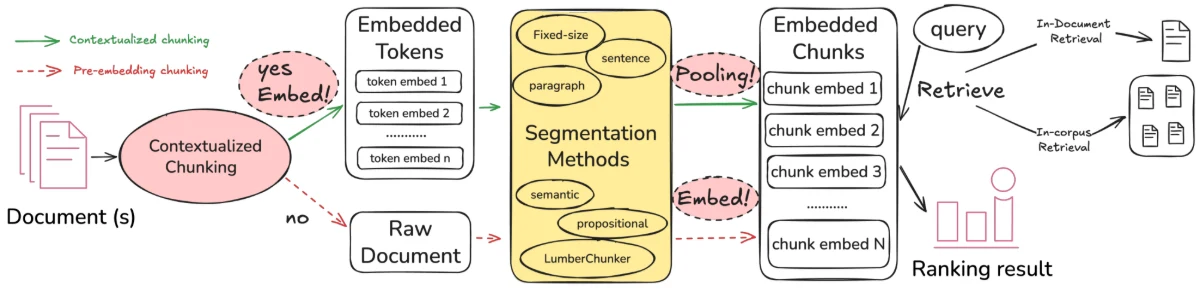
A unified framework for comparing document segmentation and embedding strategies across retrieval tasks.