Efficient RAG · 2025
COCOM
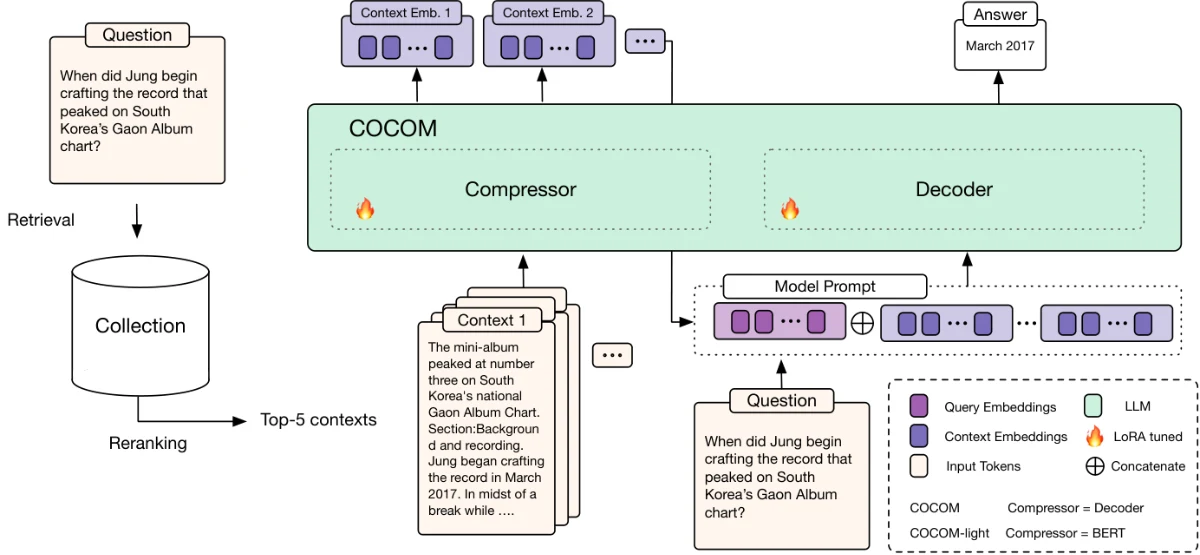
Retrieved contexts are compressed into embeddings before answer generation, connecting retrieval with efficient decoding.
Abstract
Retrieval-Augmented Generation (RAG) allows overcoming the limited knowledge of LLMs by extending the input with external information. As a consequence, the contextual inputs to the model become much longer which slows down decoding time directly translating to the time a user has to wait for an answer. We address this challenge by presenting COCOM, an effective context compression method, reducing long contexts to only a handful of Context Embeddings speeding up the generation time by a large margin. Our method allows for different compression rates trading off decoding time for answer quality. Compared to earlier methods, COCOM allows for handling multiple contexts more effectively, significantly reducing decoding time for long inputs. Our method demonstrates a speed-up of up to 5.69 × while achieving higher performance compared to existing efficient context compression methods.
Papers
2025WSDM 2025cited 91×Co-first author
Context Embeddings for Efficient Answer Generation in RAG
David Rau*, Shuai Wang*, Hervé Déjean, Stéphane Clinchant, Jaap Kamps